Top 10 AI models
| # | Model | Win rate |
|---|---|---|
| 1 | Gemini 3.5 Flash-Lite | 72.1% |
| 2 | gpt-5.6-terra | 72.0% |
| 3 | gpt-5.5-2026-04-23 | 71.8% |
| 4 | gpt-5.1 | 70.5% |
| 5 | gpt-6-astra | 69.8% |
| 6 | gpt-5.2 | 69.0% |
| 7 | gpt-5.2-2025-12-11 | 68.9% |
| 8 | gpt-5.1-2025-11-13 | 68.4% |
| 9 | gpt-5.4-2026-03-05 | 68.4% |
| 10 | gpt-6.1-sol | 67.8% |
Parallel Intelligence, Single Decision
Every question goes to several AI models at once, blind to each other. Their perspectives converge into one reliable answer.
Tokonomix is a multi-model AI consensus gateway and independent LLM benchmark. One OpenAI-compatible API key reaches every model we track; for high-stakes prompts, several frontier models answer in parallel and a cross-family judge reconciles them into one verdict — with each model's answer, tokens and cost itemised. Daily speed and quality benchmarks in six languages, published openly.
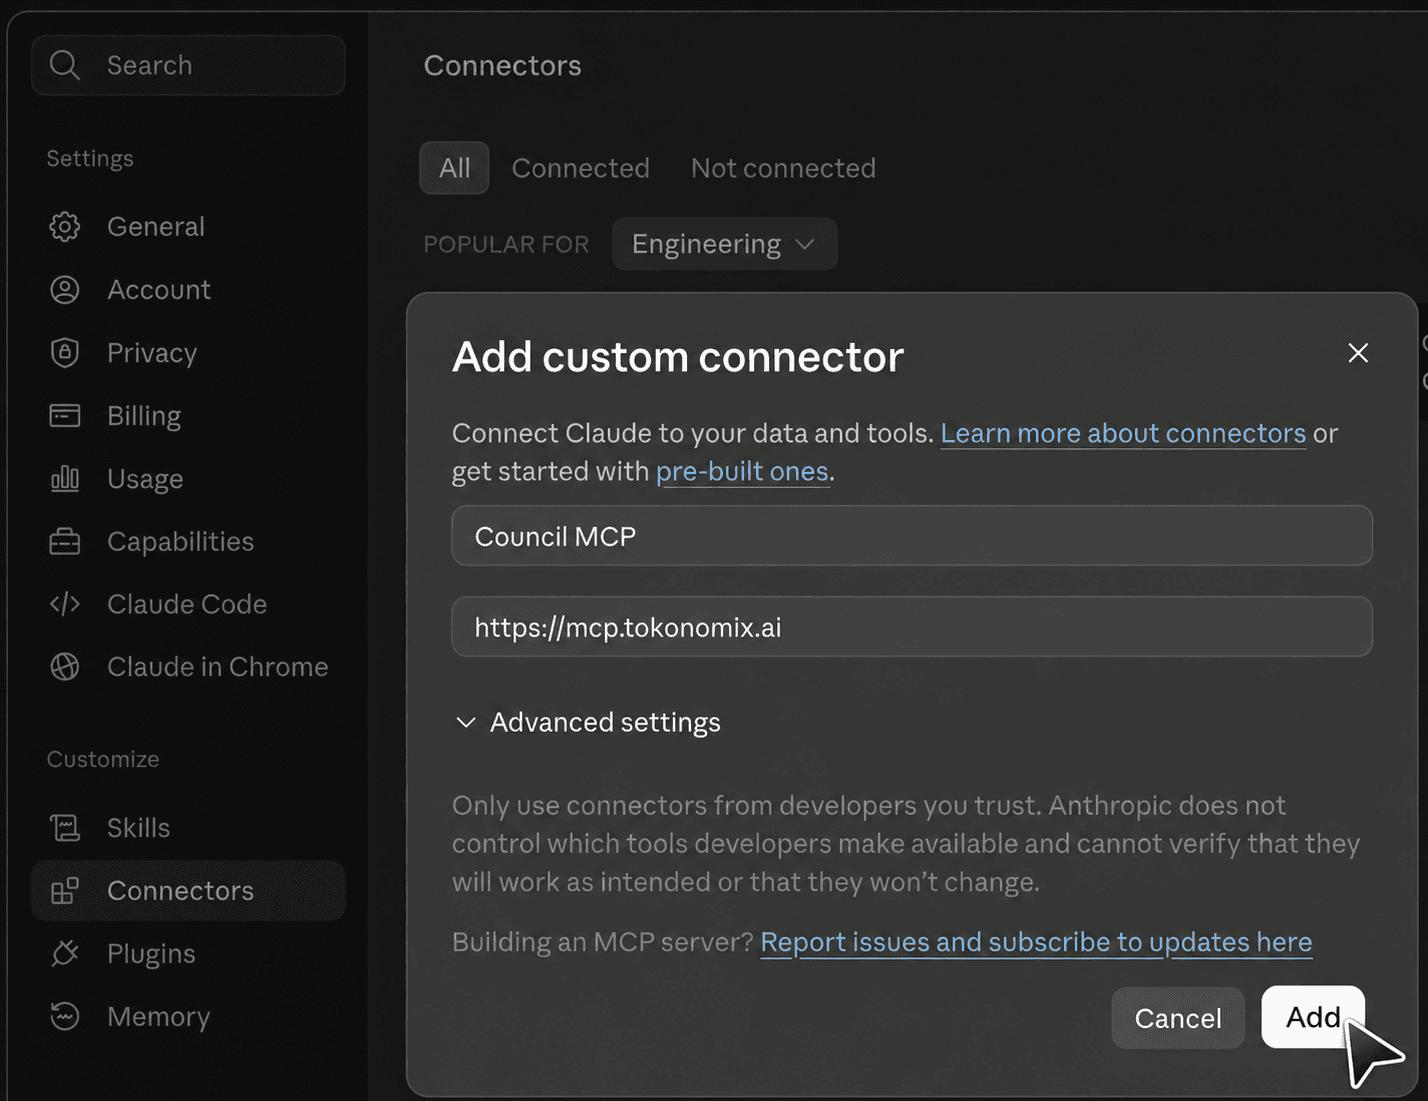
Connect the MCP
Enter a name, paste in https://mcp.tokonomix.ai, hit Add and log in through Tokonomix. From there Claude taps directly into Tokonomix's tools and data — no extra setup required.
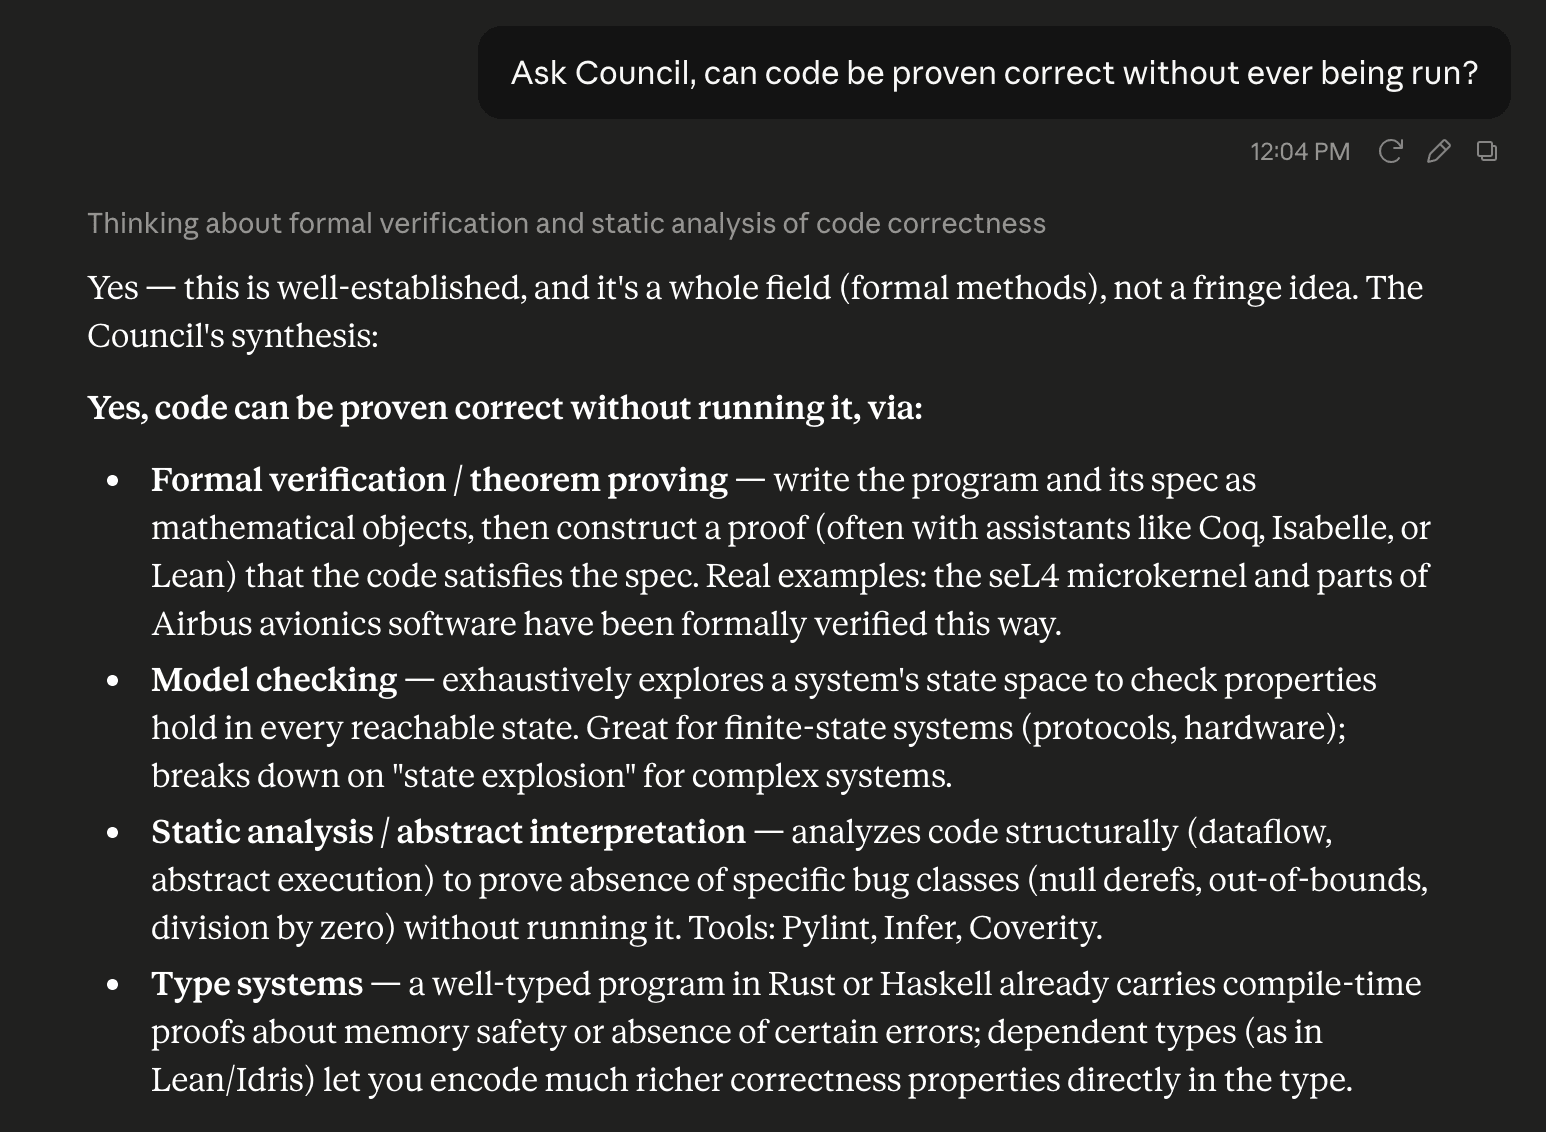
Ask the council
Send one prompt through the connector and Tokonomix fans it out to several models at once, each blind to the others. You get one verdict back — plus what every model actually said, and what the round cost.
Top models, per capability
Same prompts, same conditions, measured through our own gateway. Quality score, latency and output price side by side — pick the tab that matches your workload.
Win rate against a field-average model on this capability’s prompts — 50% is average. Not a percentage of correct answers.
Live bench
| # | Model | Provider | Win rate | Latency | Output / 1M |
|---|---|---|---|---|---|
| 01 | gpt-6-luna | OpenAI | 87.4% | 2.85s | $0.9800 |
| 02 | gpt-6-astra | OpenAI | 77.0% | 2.71s | $65.00 |
| 03 | Gemini 3.5 Flash-Lite | Google Gemini | 72.0% | 696ms | $3.74 |
| 04 | gpt-5.2 | OpenAI | 69.5% | 1.82s | $18.20 |
| 05 | gpt-4.1 | OpenAI | 67.1% | 765ms | $11.96 |
| 06 | gpt-5.1 | OpenAI | 65.0% | 2.13s | $13.00 |
7-day rolling average · last test Oct 25
Judge verdicts
7,328 evaluations across 75 models — verdict counts only, never customer prompts.
Neutral judge
Ranked on accuracy · minimum 10 judged runs
| # | Model | Verdicts | Accurate | Runs |
|---|---|---|---|---|
| 01 | Claude Opus 4.6 | 98% | 160 | |
| 02 | Claude Opus 4.5 | 96% | 160 | |
| 03 | gpt-4.1-2025-04-14 | 95% | 175 | |
| 04 | gpt-4.1-mini | 94% | 177 | |
| 05 | gpt-5.5-2026-04-23 | 94% | 86 | |
| 06 | Claude Opus 4.7 | 94% | 161 | |
| 07 | gpt-4.1 | 93% | 176 | |
| 08 | Claude Sonnet 4.5 | 93% | 161 |
Ship flawless AI images, every time.
5 AI models inspect every image for the flaws humans spot first: extra fingers, broken shadows, impossible physics.. etc.
New · early access
BETA 2026-07 · LOKI-35 + Real Control Photos · Not a Product Guarantee.
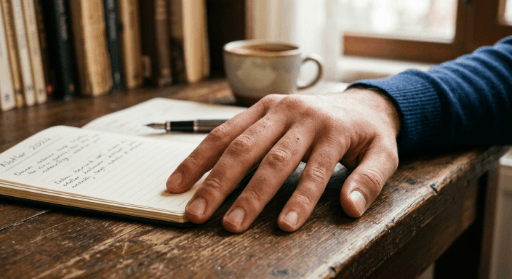
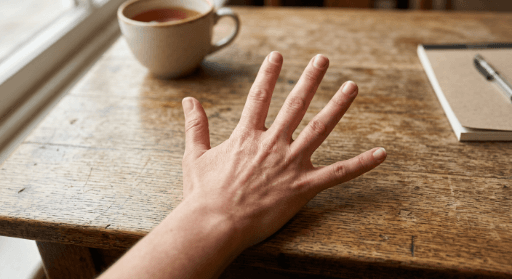
3 of 5 saw it. One model alone would have missed it — hence a council.
Pricing
Pay only for what you use
Top up a prepaid balance and every call is paid from it. No subscription, no minimum, no monthly fee.